

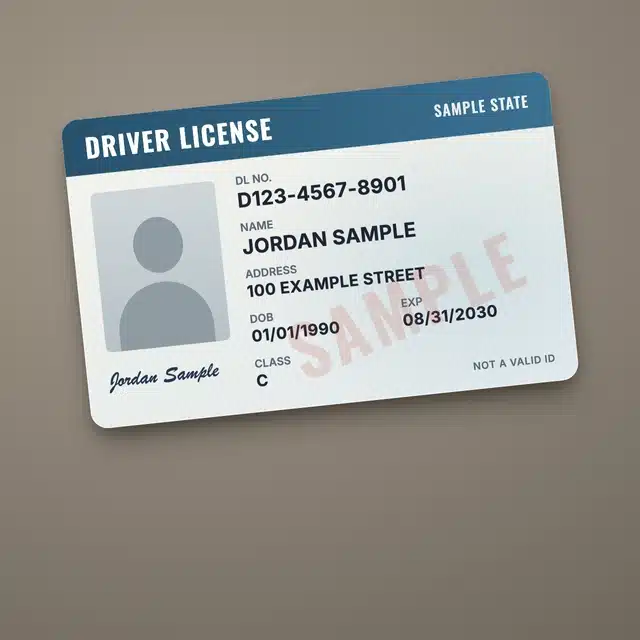
Example model output4 fields
- 1license_number
- D123-4567-8901
- 2name
- Jordan Sample
- 3expiry_date
- 08/31/2030
- 4date_of_birth
- 01/01/1990
Customized Machine Learning Models
Document data extraction with a model trained on your own documents. It returns the fields your workflow needs, by name.
Passports
- 1Portrait
- 2Passport number
- 3Machine readable zone
Driver's Licenses
- 1Full name
- 2License number
- 3Expiry date
- 1Sender
- 2Postage
- 3Delivery address
More ContentIQ Use Cases
- Check amounts from bank check images
- Medical image processing
- Plagiarism detection
- Custom objects, such as specific car makes and models
- Automated content categorization
- Advanced content moderation
ContentIQ Compared With Filestack AI
Filestack AI returns general labels for any file. A ContentIQ model returns the fields your process uses. For every line of text in a file, use the OCR API, and to route extracted fields through review and storage, see intelligent document processing.
Filestack AI
Ready-made tasks, the same for every customer.
What Filestack AI returned for this license
tags-
- credit card83
- document89
- driving license84
- id cards85
- text99
caption- “a screenshot of a cell phone”
ocr-
- DRIVER LICENSE
- DL NO.
- D123-4567-8901
- NAME
- JORDAN SAMPLE
- ADDRESS
- 100 EXAMPLE STREET
- DOB
- 01/01/1990
- Jordan Sample
- CLASS
- C
- SAMPLE STATE
- EXP
- 08/31/2030
- NOT A VALID ID
- Tasks including tags, sfw, ocr and caption
- Runs from a CDN URL or a workflow on upload
ContentIQ
A model trained on your documents and your labels.
Example fields a model returns for this license
- License number
- Name
- Expiry date
- Date of birth
- Designed, trained and managed by Filestack’s team
- Retrained through an automated feedback loop
- Delivered behind a single API
How Filestack Builds a ContentIQ Model
Customized models, delivered in a single API. Building customized machine learning models is no small task, and our expertise streamlines the process.
-
01
Define the Problem
We work with you to crystallize the problem so machine learning can solve it.
- Filestack Delivers
- Customer Collaborates
-
02
Build the Data Set
If you have the data, great. If not, we’ll help build it.
-
03
Curate the Relevant Data
Now that we have the data, we build the connections. We work together, using your knowledge of your business, so our machine learning experts build the references in a way that matches your business process.
-
04
Architecture
We build a customized architecture to run your model. With the prep work done, we pull in the technologies that match your process and then build the customized infrastructure.
-
05
Training
Our experts pair their knowledge of deep learning with your business process definition to train the models to the customized outcome you need.
-
06
Deploy
The model is trained and the architecture is in place, so it’s time to put the model to work. Under the watchful eyes of our experts, we integrate it. Continuous learning is part of the process: we set up a feedback loop to monitor the output and make sure the model always delivers the results your business requires.
We check in throughout the process to ensure the model meets your needs.
Talk to our sales team to learn how we can take the latest technology and your business process to customize an output that will save you time and money for years.
Earth Class Mail Processes Mail With Filestack

“A simple integration with Filestack’s content intelligence API allowed us to offload the analysis of a large volume of mail quickly and reliably. This automation has proven critically important as our team has more time to focus on enhancing our core product.”
Steven Maguire, VP Technology at Earth Class Mail
Frequently Asked Questions About ContentIQ
What is ContentIQ, and how does it work?
ContentIQ is Filestack’s machine learning service that delivers tailored models through a single API. Filestack’s team designs, trains and manages a model built around your business process, and your application calls it to analyze the content your users upload.
How is ContentIQ different from Filestack AI?
Filestack AI runs ready-made tasks on any file, such as image tagging, safe-for-work detection, OCR and captioning. A ContentIQ model is trained on your own content and returns the labels or fields your business defines, such as the license number on a driver’s license or a specific car make and model.
What can a ContentIQ model be trained to do?
Each model is built for one use case. Examples include reading scanned envelopes, recognizing check amounts from bank check images, processing government IDs, medical image processing, plagiarism detection, custom object recognition, content categorization and content moderation.
Can ContentIQ extract data from documents?
Yes. Document data extraction is the most common ContentIQ project. A model trained on your passports, driver’s licenses, envelopes or forms returns each field by name, such as the license number on a driver’s license. For the full text of a document, use the Filestack OCR API.
Who builds and trains a ContentIQ model?
Filestack’s machine learning engineers and data scientists curate the data set, build and train the model, and deploy it behind a single API. Your team defines the problem and reviews the model at every step.
Does a ContentIQ model improve after launch?
Yes. An automated feedback loop retrains and fine-tunes the model as it processes more of your data.
How does ContentIQ connect to file uploads?
ContentIQ runs on the same platform as Filestack uploads and workflows, so a model can analyze files as your users upload them. Your application adds it with a few lines of code.
How do I start a ContentIQ project?
Talk to Filestack’s sales team about the problem you want to solve. The project starts by defining that problem, then building the data set from your data or with Filestack’s team.